Run the same passage through GPT, Gemini, Claude, DeepSeek, DeepL, and Google Translate, and you will often get several perfectly readable translations — but rarely the same one.
One may stay closer to the source. Another may sound more natural. A third may handle context better, while another returns the result noticeably faster.
As more AI models become capable of translation, the question “Which AI translator is best?” has become harder to answer with a simple ranking.
A 2026 EAMT study evaluated 15 large language models across 22 translation directions and found that performance was consistently weaker for non-English-centric language pairs than for English-centric ones. MuBench, published at ACL 2026, expanded multilingual evaluation to 61 languages and likewise found a gap between the languages models claim to support and the quality they actually deliver.
In other words, strong results on an English-focused benchmark do not automatically mean a model will perform equally well across every language pair or type of content.
SelectTranslate currently supports more than 20 translation services and AI models, including Google Translate, Microsoft Translator, DeepL, GPT, Gemini, Claude, DeepSeek, Qwen, and GLM. With that many options, the more useful question is not which model is permanently “number one,” but how to tell which one fits the content you are working with.
How to Choose an AI Translation Model: Start With These 6 Factors
You do not need to test a dozen models every time you translate something. Start by identifying what matters most for the task, and the shortlist usually becomes much smaller.
| Factor | What to Check |
|---|---|
| Language pair | How consistently the model performs for the exact source and target languages you use |
| Semantic accuracy | Whether it introduces mistranslations, omissions, additions, or shifts in meaning |
| Context handling | Whether references, ambiguity, and surrounding sentences are interpreted correctly |
| Terminology consistency | Whether the same technical concept is translated consistently throughout the text |
| Structural fidelity | Whether code, tags, formulas, placeholders, and formatting remain intact |
| Speed and cost | Whether latency and long-term usage costs are acceptable for the task |
There is no fixed order of importance.
When reading a news article, waiting several extra seconds for slightly more polished wording may not be worth it. In a 40-page technical document, however, one inconsistent term can make the entire document harder to follow. For live subtitles, even an excellent translation becomes frustrating if it consistently appears several seconds after the speaker.
The real question is whether the model’s strengths match the job.
Why AI Translation Rankings Have a Short Shelf Life
Translation benchmarks can be useful for narrowing down candidates, but they are much less reliable as permanent leaderboards.
Language is the first reason.
The 2026 EAMT study tested 15 LLMs across 22 translation directions and found that COMET scores were consistently lower for non-English-centric pairs. It also observed a relationship between how efficiently models represent particular languages and how well they translate them.
MuBench looked at the problem on a larger scale. Its dataset contains roughly 3.9 million samples across 61 languages, with language experts providing human evaluations of translation quality and cultural sensitivity for around 34,000 samples in 17 languages. The results showed that real multilingual performance still varies substantially by language, particularly between English and lower-resource languages.
The way translations are evaluated matters too.
An ACL 2026 study on non-literal translation used 7,530 human quality judgments and found that traditional machine translation metrics can struggle with content such as literature and social media, where literal equivalence is not always the goal. Using an LLM as a translation judge introduces its own limitations, including inconsistent scoring and knowledge-boundary effects.
So benchmarks are useful for answering:
Which models are worth testing?
They are much less useful for answering:
Which model should I use for everything from now on?
GPT, Gemini, Claude, and DeepSeek Are Not the Same Kind of Tool as DeepL or Google Translate
Another source of confusion is that these products do not all come from the same technical lineage.
GPT, Gemini, Claude, and DeepSeek are general-purpose large language models. Translation is one of many things they can do. They can also use instructions about context, terminology, audience, tone, and style when producing a translation.
DeepL and Google Cloud Translation, by contrast, have product lines built specifically around machine translation and multilingual workflows.
Google’s own translation stack illustrates the difference well. Cloud Translation currently offers both Neural Machine Translation (NMT) and a Translation LLM. Google positions NMT as its fastest option for real-time and latency-sensitive use cases, while its Gemini-powered Translation LLM is optimized more heavily for translation quality and customization.
Broadly, today’s translation options fall into three groups:
| Approach | Typical Strengths |
|---|---|
| Dedicated machine translation | Low latency, stability, and high-volume language conversion |
| Translation-focused LLMs | A balance between contextual reasoning and purpose-built translation, with additional customization |
| General-purpose LLMs | Translation combined with context, terminology, tone, and complex instructions |
These approaches are not simply a case of “new technology replacing old technology.”
The fact that Google continues to offer both NMT and an LLM-based translation model reflects a real trade-off between latency, quality, customization, scale, and cost.
Technical Content Has Another Problem: The Translation Must Not Break the Structure
Technical documentation and academic papers are useful stress tests because many of their problems do not show up in ordinary sentences.
A technical term may appear dozens of times throughout a document. If it is translated one way on page one and another way on page fifteen, every individual sentence may still look reasonable while the document as a whole becomes harder to understand.
Technical content also introduces another requirement: the structure itself needs to survive translation.
Markdown syntax, code blocks, HTML or XML tags, variables, placeholders, and LaTeX formulas should not be treated like ordinary prose. Preserving them correctly depends not only on the underlying model, but also on how the translation system identifies, protects, and restores structured content before and after translation.
Dedicated translation APIs already provide mechanisms for this.
Google Cloud Translation supports HTML input and translates the text between tags while preserving the HTML structure. It also provides ways to mark content that should not be translated.
DeepL’s API likewise supports HTML and XML tag handling, ignore_tags, and formatting-preservation controls.
For developer documentation, research papers, or other structured material, translation quality therefore means more than whether a sentence sounds natural.
You should also check whether terminology drifts, whether code or formulas are modified, whether tags remain valid, and whether meaning stays consistent across multiple paragraphs.
Video Subtitles Follow a Completely Different Set of Priorities
Now replace a technical document with live or recorded video subtitles, and the priority order changes immediately.
Subtitles are usually short, but they appear continuously and depend heavily on what came before. A speaker may omit a subject, use a pronoun that refers to an earlier sentence, or split one thought across several subtitle segments.
If the translation model ignores previous context, references can easily become ambiguous or wrong. But if it waits too long for additional context, the translation falls behind the video.
For subtitles, translation quality is therefore a combination of three things:
accuracy, contextual continuity, and timing.
A more sophisticated model does not automatically create a better viewing experience if it introduces noticeably more latency.
Google’s distinction between low-latency NMT and a more quality- and customization-focused Translation LLM is a useful example of this trade-off.
Technical documents and real-time subtitles alone are enough to show why there is no single definition of the “best” translation model.
A Better Approach: Test Models With Your Own Content
If you expect to use a translation model regularly, a small real-world test is usually more useful than another “Best AI Translator of 2026” list.
You do not need a professional benchmark or ten different models.
Step 1: Use Real Material
Choose content you genuinely work with.
For example:
- a Japanese product announcement;
- an English technical document;
- several Korean subtitle lines;
- a Spanish customer email;
- a page from a research paper containing domain-specific terminology.
Do not limit the test to English-to-Chinese or any other single direction. Test the language pairs you actually encounter.
Step 2: Keep the Conditions Consistent
Each candidate model should receive roughly the same information.
If GPT receives full context while another model receives only one isolated sentence, the results are not meaningfully comparable.
Keep the source language, target language, surrounding context, and basic translation instructions as consistent as possible.
Step 3: Look for Errors Before Judging Style
A useful evaluation order is:
mistranslations and omissions → terminology → context → structure → fluency
A translation can sound excellent while quietly changing the meaning of the source.
For research papers, technical documentation, contracts, and other high-stakes material, semantic accuracy should usually come before stylistic polish.
Step 4: Test Several Consecutive Passages
A single difficult sentence is rarely a good benchmark.
Several consecutive paragraphs are much more likely to expose terminology drift, broken references, inconsistent subjects, or loss of context — problems that isolated sentence tests tend to miss.
Step 5: Compare Speed and Cost Last
If two models produce similarly good translations, latency and price may become the deciding factors.
That difference may not matter when translating a few paragraphs a day. It becomes much more important when continuously translating web pages, subtitles, or large collections of documents.
What Should Matter Most for Different Translation Tasks?
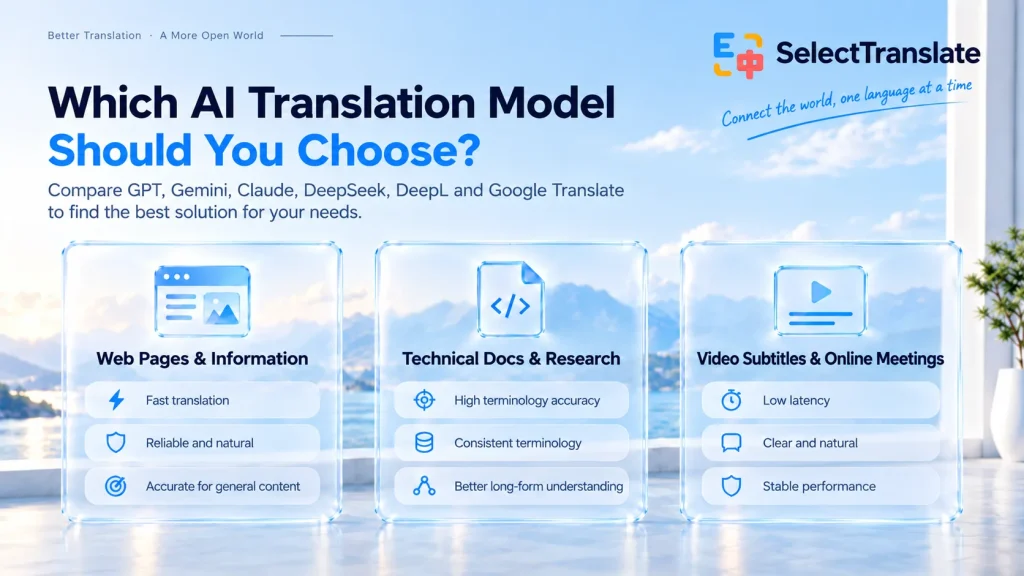
For common use cases, the priorities can be simplified:
| Content Type | What to Prioritize |
|---|---|
| General web pages, news, forums | Speed, stability, baseline accuracy |
| Technical documentation and research papers | Semantic accuracy, terminology consistency, structural fidelity |
| Video subtitles and online meetings | Latency, context continuity, stability |
| Email and chat | Meaning, tone, natural expression |
| Marketing and localization | Native-language quality, style, cultural fit |
| High-volume translation | Cost per unit, throughput, stability |
| Non-English or fixed language pairs | Actual performance on that specific language direction |
This approach also ages better than a fixed model ranking.
When a new version of GPT, Gemini, Claude, or DeepSeek arrives, you do not need to rebuild your entire decision framework. You simply put the new model through the same real-world test and see whether it improves the factors that actually matter to you.
Why SelectTranslate Supports Multiple Translation Models
A long model list by itself does not make a translation tool better.
The useful part is having different ways to respond when a particular translation problem appears.
If a technical document repeatedly uses the same domain-specific terminology, a termbase can help keep approved translations consistent across the content.
If certain types of content need specific translation rules, AI Expert can apply domain-specific roles and prompts instead of treating every page the same way.
And when several models produce noticeably different translations, Optimal Translation can generate results from multiple models, score them, and still allow you to inspect or switch between the individual outputs.
Automated model scoring should not be treated as a substitute for human judgment. Research on LLM-as-a-Judge evaluation in machine translation continues to show that model-based scoring can be inconsistent.
Its practical value is simpler: it reduces the amount of manual switching required when the first translation is not good enough.
That is the real advantage of supporting multiple models.
Not:
“Which model is always the best?”
But:
“If this result is not right for the current content, do I have another option?”
The Best Translation Model Depends on the Content
GPT, Gemini, Claude, DeepSeek, DeepL, and Google Translate will continue to change. A model that leads a benchmark today may no longer lead after a new release, a different language pair, or a different test set.
The selection process does not need to change nearly as often.
Start with the languages you actually use. Identify whether the content is a web page, technical document, subtitle stream, meeting, or conversation. Then decide whether accuracy, terminology, context, structure, speed, or cost matters most.
From there, test two or three plausible candidates with real content.
For general web reading, fast and reliable translation may be enough. For a technical paper, one corrupted formula or inconsistent term may matter far more than an extra second of latency. For live subtitles, latency itself becomes part of translation quality.
The right translation model is not necessarily the one that tops a leaderboard. It is the one that consistently solves the problem in front of you.
Frequently Asked Questions
Which is better for translation: GPT, Gemini, Claude, or DeepSeek?
There is no single answer that applies to every language and type of content. Performance can vary by language pair, context, and task. For languages you use frequently, the most reliable approach is to test two or three candidate models on the same real-world material under the same conditions.
What is the difference between DeepL and LLMs such as GPT?
DeepL has built its core products around translation and professional language workflows. GPT, Claude, Gemini, and DeepSeek are general-purpose language models that can also translate while following instructions about context, tone, terminology, and style. Their capabilities overlap, but their product goals and workflows are not identical.
Are large language models always better than traditional machine translation?
No. Google Cloud still offers both NMT and an LLM-based translation model, with different priorities around latency, quality, and customization. Dedicated machine translation remains highly practical for real-time and high-volume workloads.
How should I choose a model for non-English or lower-resource languages?
Do not rely solely on English-focused benchmarks. Multilingual research published in 2026 continues to show larger performance gaps for non-English-centric and lower-resource language directions. Test the exact source and target languages you need using several consecutive real examples, and check for mistranslations, omissions, proper names, context, and natural target-language expression.
What should I check when translating code or technical documentation?
In addition to accuracy and terminology, check whether Markdown, code blocks, HTML/XML tags, variables, placeholders, and formulas remain intact. Structural preservation depends not only on the model, but also on whether the translation tool correctly identifies and protects non-translatable content.
What matters most when translating research papers?
Start with semantic accuracy, terminology consistency, and cross-paragraph context rather than judging only whether individual sentences sound fluent. For papers containing formulas, tables, or complex layouts, structural preservation and document parsing also matter.
Why do different AI models translate the same sentence differently?
Models differ in training data, language representation, context handling, and generation behavior. Many phrases also have more than one valid translation. The more a passage depends on ambiguity, domain terminology, spoken language, or surrounding context, the more visible those differences tend to become.